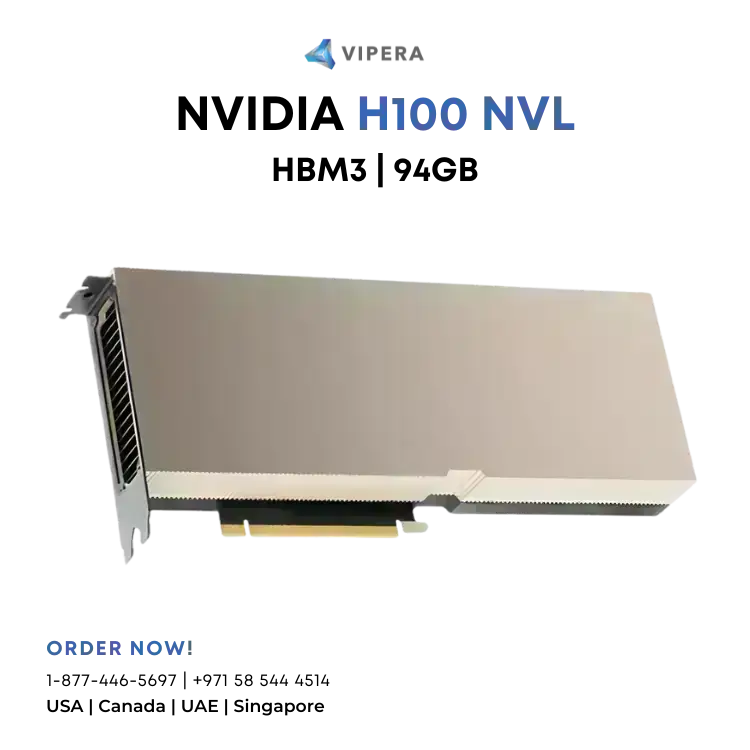
Overview
The NVIDIA H100 NVL is a Hopper-architecture PCIe AI accelerator with 94GB HBM3 memory via a full 6144-bit memory bus, delivering up to 12× faster inference than A100 for GPT-3-scale models. Passively cooled at 350W via PCIe, it provides enterprise-grade Transformer Engine acceleration for large language model deployment without requiring SXM infrastructure.
Key Features
- 94GB HBM3 via full 6144-bit memory interface
- Hopper architecture with Transformer Engine for LLM acceleration
- Up to 12× faster GPT-3 inference vs prior-gen A100
- Passive cooling at 350W via PCIe — no SXM fabric needed
- 132 Streaming Multiprocessors for massive parallel compute
Ideal For
Enterprise AI teams deploying large-scale LLMs at datacenter scale in PCIe-compatible servers without requiring SXM4 NVLink fabric infrastructure.
This vendor publishes no specification table. The following is derived from the product listing.
- GPU / accelerator
- H100
- GPU count
- 1
- GPU memory
- 94GB
- Form factor
- pcie-card
- Power supply
- 350W
$32,200.00
Prices may vary. Verify on vendor site.
Tags
llm-inferencellm-traininggenerative-aihpcdata-analyticssmall-modelmedium-modellarge-model